
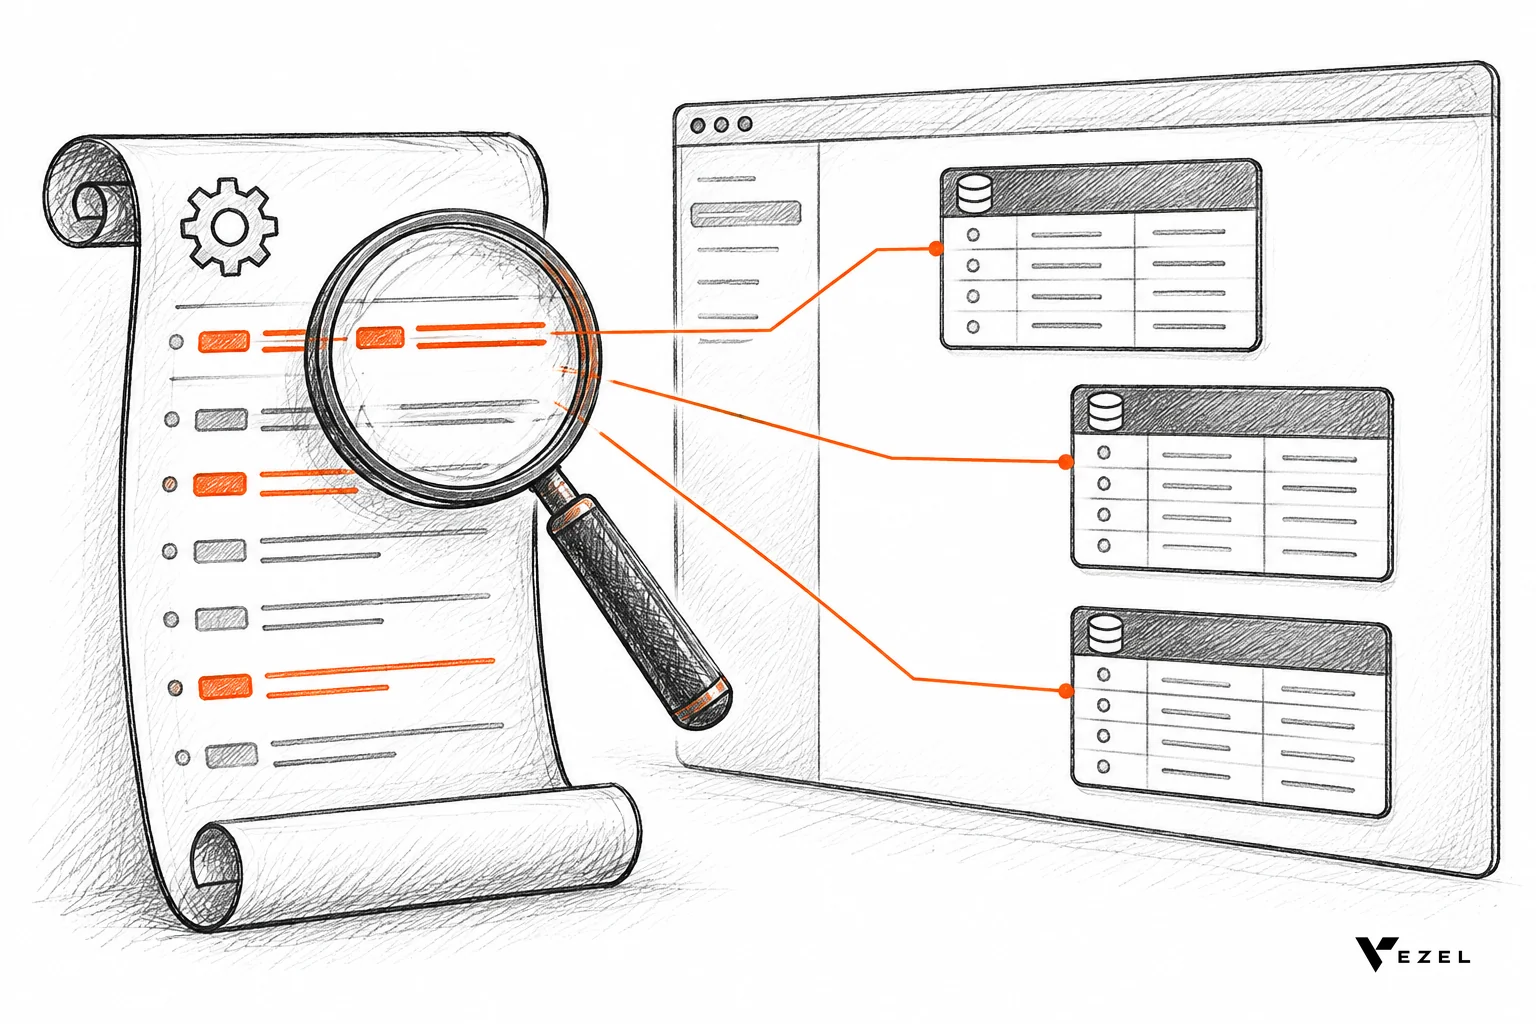
API auto-discovery OpenAPI mapping is the step where an extension platform reads your OpenAPI spec, lists every endpoint and schema, and matches them to the data models already in your product. For US SaaS teams, the safe order is checks first: confirm the spec matches live endpoints, confirm inherited permissions, then publish through governance.
Key takeaways
- The spec is the map: discovery only knows what your OpenAPI file declares, so a stale or incomplete spec produces extensions that point at nothing real.
- Check before you build: compare spec to live responses, confirm schema names match your data models, and settle pagination and error behavior before anyone generates an extension.
- Permissions must match the host UI: test with at least two roles and confirm each sees exactly the rows and actions they see in your product today. Any mismatch blocks rollout.
- Govern from day one: publishing, approvals, versions and retirement belong in a central control plane, and a spec change should trigger a re-scan.
- Timeline: most SaaS platforms can integrate Vezel in a few days, and the prep work in this guide is what keeps those days uneventful.
API auto-discovery and OpenAPI mapping at a glance
| Stage | What happens | Pass mark before moving on |
|---|---|---|
| 1. Spec intake | Platform reads paths, operations, parameters and schemas from your OpenAPI file | File parses with no errors and covers the endpoints customers actually use |
| 2. Model mapping | Schemas and operations are matched to your existing entities and relationships | Every mapped entity has a read operation and a clear owner on your team |
| 3. Endpoint verification | Spec is compared against live responses | Field names, types and status codes match production; walk away if core entities drift |
| 4. Permission test | Extensions run under the signed-in user's authentication, RBAC and row-level rules | Two or more roles see the same rows as in the host product |
| 5. Governance setup | Publishing, approvals and versions are set in the control plane | Nothing reaches customers without a named approver and a version tag |
| 6. Staged rollout | A pilot group uses extensions before general release | No permission or data mismatch reported during the pilot |
What happens when a platform scans your OpenAPI spec?
The platform parses your OpenAPI file and builds an inventory: every path, the operations on it (read, create, update, delete), the parameters each accepts, and the schemas describing request and response bodies. That inventory becomes the list of things an extension is allowed to call.
The OpenAPI format exists for this kind of reuse. As Wikipedia's OpenAPI Specification entry notes, applications can use OpenAPI descriptions to automatically generate documentation of methods, parameters and data models. Discovery applies the same idea to extensions instead of docs.
Three points matter for engineering leads. First, discovery is read-only against the spec; it does not need to change your core application. This is what a zero footprint integration means in practice: no new code or schema inside your product.
Second, the scan only sees what the file declares. An endpoint that exists in production but not in the spec is invisible, and an endpoint in the spec that was removed from production is a trap. Third, the spec is a contract, so its quality sets the ceiling for everything built on top.
If you want the beginner version of the concept first, our API auto-discovery explainer covers the basics. This guide assumes you are about to run it against a real product.
What the scan produces
- Endpoint inventory: paths, methods and parameters, grouped by resource.
- Schema catalog: named objects with field types, required fields and nested references.
- Capability candidates: reads that can feed dashboards and reports, writes that can feed forms, approvals and automations.
- Gaps list: operations with no schema, missing descriptions or unclear auth requirements.
Treat the gaps list as your first to-do list. Every item on it is a place where a generated extension would have to guess.
How does OpenAPI mapping connect endpoints to your data models?
Mapping pairs each schema in the spec with an entity in your product, such as Account, Invoice or Work Order, then links the operations that read or change it. References between schemas become relationships, so the platform knows an Account has Renewals and can build views that join them.
Here is a hypothetical example, not a customer case. Suppose a CRM spec declares an Account schema, a Renewal schema that references an account ID, and a list operation for each. Discovery maps both to your existing entities and records the relationship.
A customer success lead can then type a plain-English request for a renewal workspace sorted by days to renewal. The platform has a valid, declared path to the data and does not invent fields. Our guide to connecting AI extensions to your SaaS APIs shows the connection side in more detail.
Where mapping gets ambiguous
Mapping is clean when names are consistent. It gets shaky in four places:
- Duplicate concepts: two schemas that both look like a customer, such as
AccountandOrganization. - Loose types: fields declared as free-form objects, so the platform cannot tell a date from a string.
- Hidden relationships: foreign keys stored as plain strings with no reference to the parent schema.
- Action endpoints: verbs such as
/approvethat change state without a standard create or update shape.
Resolve each by tightening the spec, not by teaching the platform your quirks. A clearer spec helps your docs, your SDKs and your partners too. It also keeps the mapping reviewable by a human, which matters when the output goes to customers.
This is the same pattern described in the OpenAPI Initiative's case study on integrating SaaS applications at scale, where a team built ingestion logic that calls each provider's APIs from a spec description. A common, machine-readable description is what makes the work repeatable.
Pre-rollout checks so extensions match real endpoints
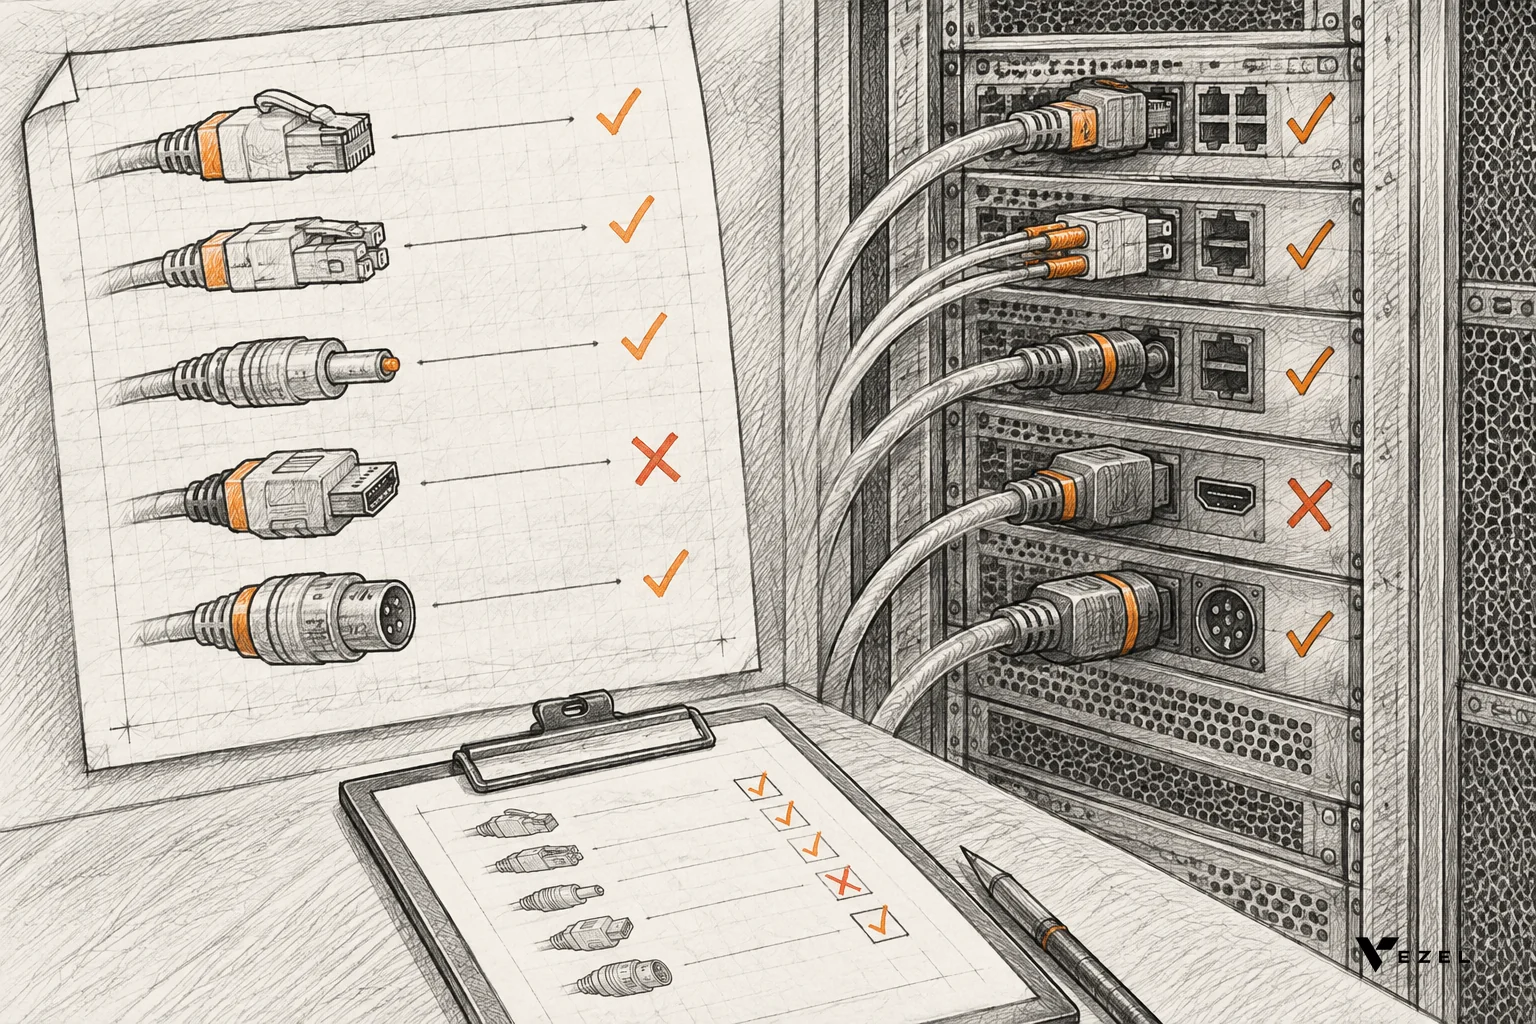
Run these checks in order, before anyone generates an extension for customers. Each has a pass mark and a walk-away condition, because a check with no failure rule is only a suggestion.
1. Compare the spec to live responses
Call a sample of read endpoints in a staging environment and compare responses to the declared schema. Check field names, types, required fields and status codes. Pass: everything for the entities customers use most matches. Walk away: if core entities such as accounts, orders or tickets differ, fix the spec or the API first.
2. Confirm the spec covers what customers actually use
List the five to ten screens or reports your customers rely on and trace each to its endpoints. Pass: every one has a declared path. If it fails: add the missing paths to the spec, or exclude that area from the first release and say so in your rollout notes.
3. Check naming and ownership
Each mapped entity needs one canonical schema and one team that owns it. Pass: no entity has two competing schemas. If it fails: pick the canonical one and mark the other as deprecated in the spec before mapping.
4. Test pagination, filters and limits
Dashboards pull lists. Confirm that list endpoints paginate consistently, accept the filters the spec declares, and return clear errors when limits are hit. Pass: one pattern across resources. If it fails: document the exceptions and restrict generated views on those resources until they are fixed.
5. Mark sensitive and write operations
Separate reads from writes and flag any operation that deletes data, moves money or changes access. Pass: writes are individually listed and each has an approver. If it fails: start with read-only capabilities and add writes later.
6. Settle error behavior
An extension needs to show something sensible when an endpoint returns 403, 404 or 429. Pass: errors follow the declared shape. If it fails: expect broken-looking extensions, which defeats the white-labeled, native feel.
| Check | Evidence to collect | Walk-away signal |
|---|---|---|
| Spec vs live responses | Side-by-side diff for core entities | Core fields or types differ |
| Coverage | Screen-to-endpoint trace | A top screen has no declared endpoint |
| Naming and ownership | One schema and one owner per entity | Two competing schemas |
| Pagination and filters | Test calls on each list endpoint | Different patterns per resource with no documentation |
| Write operations | Flagged list with approvers | Destructive writes with no approver |
Confirming inherited authentication, RBAC and row-level permissions
Extensions inherit your existing authentication, permissions and access controls. That is the design, but inheritance is a claim you verify rather than assume. The goal is simple: an extension must never show a user anything the host product would not show them.
Skip the theory and run a role test. It takes an afternoon and catches the problems that cost deals later.
- Pick three test users: one admin, one standard user, and one restricted user such as a regional manager or a single-department user.
- Build one read extension: for example, a list of accounts with owner and status.
- Open it as each user: count the rows and note the visible fields.
- Compare with the host UI: the same three users should see the same rows and fields in your normal screens.
- Try a write as the restricted user: the action must be refused the same way your product refuses it.
Pass mark: row counts and visible fields match for every role, and refused actions stay refused. Walk-away: any user seeing one extra row, one extra field or one allowed action they lack in the product. Stop, fix the underlying endpoint rule, and rerun.
Row-level rules deserve the most attention in multi-tenant products. If tenant scoping lives in the API layer, extensions follow it. If it lives only in front-end code, the API may return more than the screen shows, and discovery will faithfully map that wider surface. Move the rule to the API before rollout.
For the deeper design questions, see our write-ups on connecting extensions to your APIs and the earlier RBAC walkthrough in our library. Keep security reviews to what you need to sign off: identities, roles, rows, actions.
Governance: publishing, versioning and lifecycle control
Publishing, permissions, approvals and the extension lifecycle are managed from a central control plane. Governance is where a good mapping stays good after the first month, because specs change and customers keep building.
Publishing and approvals
Decide who can publish an extension to a single customer, to all customers, or to an in-product marketplace. Give write-capable extensions a named reviewer. A simple rule works well: reads can publish with one approval, writes need two, and anything touching access settings is blocked by default.
Versioning
Tie each extension to the spec version it was generated against. When you ship a new API version, the platform should re-scan and flag extensions that use changed or removed operations. Pass mark: every live extension shows its spec version and owner. Fail condition: an extension with no version tag; pull it from the marketplace until it has one.
Lifecycle control
Plan for retirement on day one. Extensions that nobody uses, or that depend on deprecated endpoints, should move to a retired state with a notice period instead of breaking quietly. Our guide on reducing SaaS engineering backlog from enterprise requests explains why this governance layer is what keeps self-serve building from turning into a new support burden.
One thing is genuinely unsettled across the industry: how often to re-scan. Some teams re-scan on every spec merge, others on release. We lean toward every release for most teams, since it ties the check to a moment someone already reviews, but a fast-moving API may justify more.
Rollout steps in order
With the checks passed and governance configured, the rollout itself is short. Vezel's own flow runs in four moves: connect to your APIs, generate extensions from plain English, run them ready to use in a secure container, then scale and govern. Most SaaS platforms can integrate Vezel in a few days.
- Freeze the spec version: tag the OpenAPI file you tested against.
- Connect and scan: run discovery and review the gaps list line by line.
- Approve the mapping: have the entity owners sign off on the schema-to-model pairs.
- Apply theming: match the host design system so extensions look native.
- Run the role test again: use production-like data, not only sample records.
- Pilot with a small group: pick one friendly customer or an internal team and watch for mismatches.
- Release in stages: expand by customer group, keeping the previous state recoverable.
If you also plan to embed approval flows, the same preparation applies; see how to embed a workflow builder in your SaaS.
Common mapping problems and what to do
| Problem | Symptom in an extension | Fix |
|---|---|---|
| Spec drift | Empty columns or failed calls after an API release | Regenerate the spec from code and re-scan on each release |
| Undocumented endpoint | Customer asks for data the platform cannot reach | Add the path and schema, or decline the request |
| Loose schema types | Dates shown as text, sums that do not add | Declare exact types and formats |
| Front-end-only permission rule | Extension shows more rows than the screen does | Move the rule to the API layer |
| Inconsistent pagination | Dashboards show only the first page | Standardize or restrict those resources |
FAQ
Does the spec have to be perfect before we start?
No, but the entities customers use most must be accurate. A spec that is correct for accounts, orders and tickets and incomplete for rarely used admin areas is fine for a first release. Scope the first release to the accurate parts and document what is excluded.
How does this apply to a headless forms API for multi-tenant SaaS?
A forms capability needs declared operations to fetch field definitions, validate and submit entries, each scoped to the tenant. If your spec declares those and tenant scoping is enforced at the API, generated forms follow the same rules. Run the role test on a form submission as well as on reads.
What does "SaaS discovery" mean here?
In this context it means discovering your product's own API surface: the endpoints, schemas and relationships an extension platform can safely use. It is not a scan of other tools a customer runs. The output is an inventory, a mapping and a gaps list.
How long does integration take?
Most SaaS platforms can integrate Vezel in a few days. Preparing the spec and permissions beforehand is where teams spend the real effort, which is why the checks come before the rollout steps.
Next step
Discovery is only as good as the spec and permissions beneath it, so start with the checks and let the rollout follow. If you want to see an OpenAPI scan mapped to a real product, book a demo and share a demo account, and Vezel will create a working proof of what is possible inside your SaaS. You can also review how it works first. Questions get a reply within 1-2 business days at hello@vezel.ai.